BlogOctober 19, 2026
Does AI Read Reddit for Your Brand? Category and Model Decide
Ambika SharmaFounder at Pulp Strategy Communications and NeuroRank.
Founder at Pulp Strategy Communications and NeuroRank.
Subscribe for Newsletters
In the AI Visibility Index 2026, 41 of 63 complete-four-model audits had at least a 30-point span between highest and lowest observed High-inclusion rates. The prompt panels differed, so this is directional evidence for checking platform coverage, not a controlled comparison on identical questions.
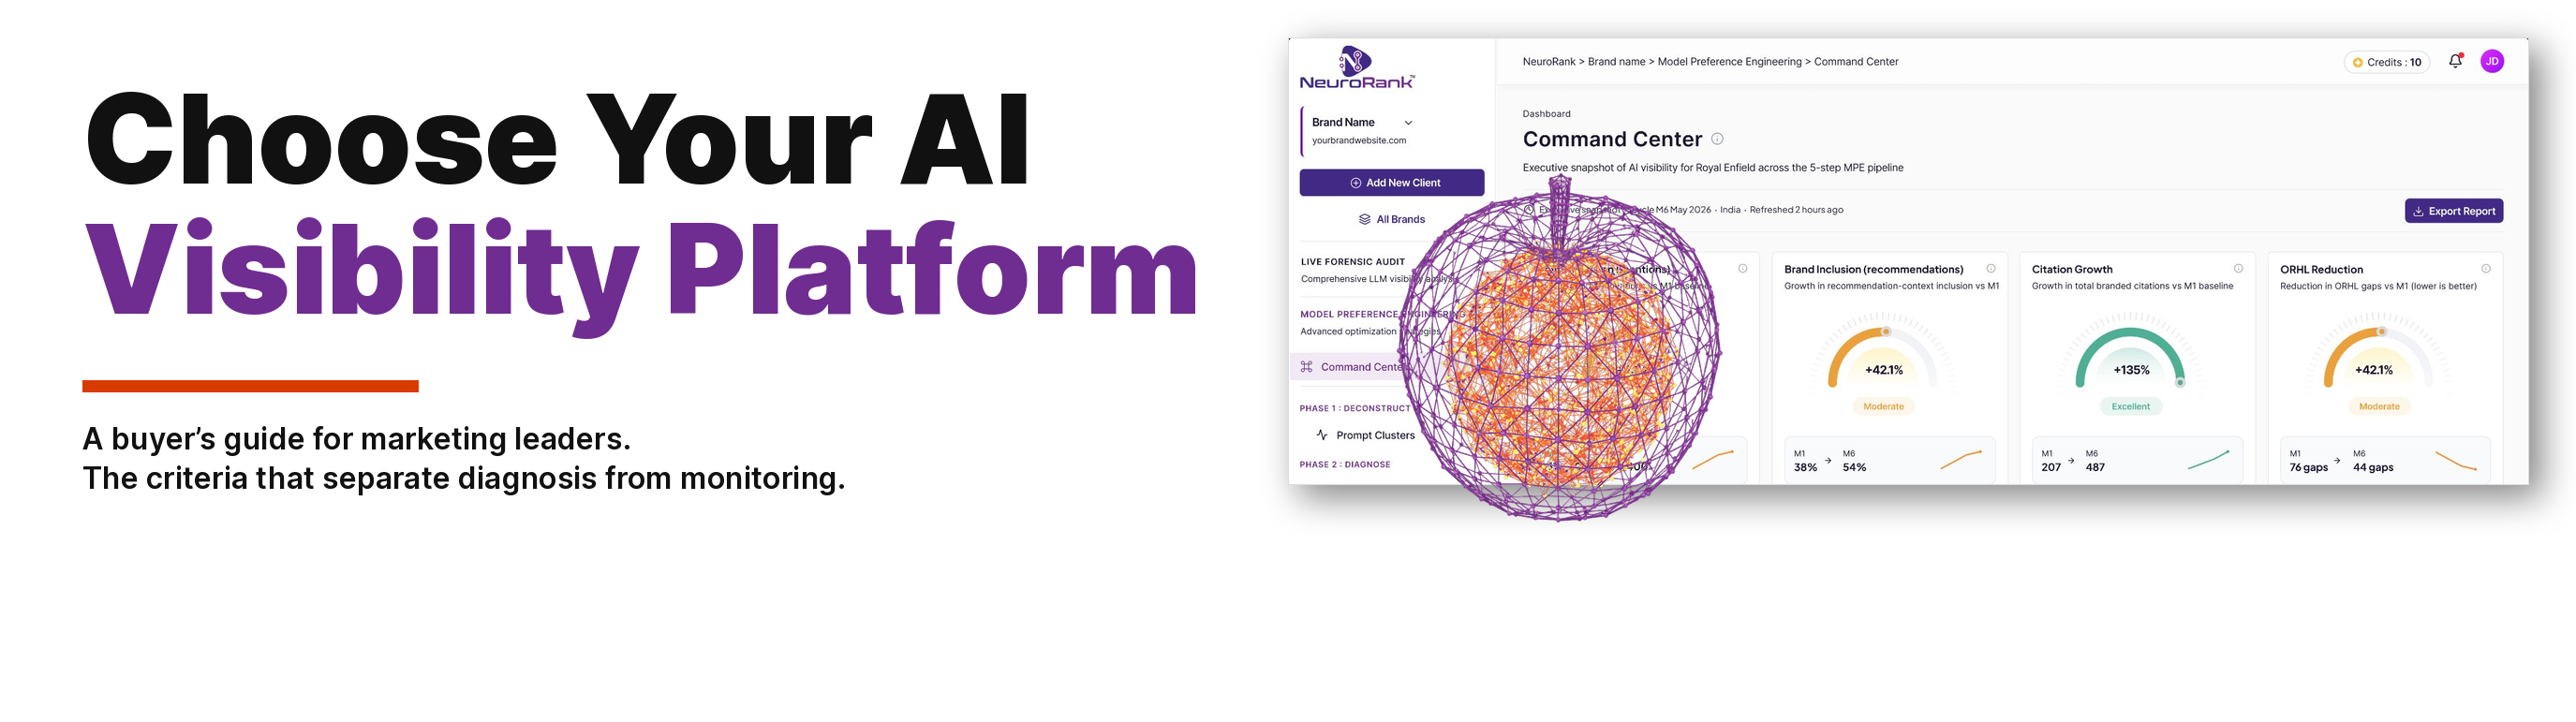
How to choose an AI visibility platform: look past whether it reports your presence and ask whether it closes the loop. Does it diagnose why you are absent, prescribe the fix, condition the sources, and track the movement? A platform earns its budget when it turns a visibility number into action across ChatGPT, Gemini, Claude, and Perplexity. Here is what to compare, and the questions to put to every vendor.
Compare the documented workflow with the work your team needs: response capture, source review, diagnosis, implementation planning, and remeasurement. Ask for a dated sample and the exact plan scope. NeuroRank supports this sequence; the client or agency carries out the source changes.
Ask what the platform actually measures. A single blended score hides the gaps that cost you. Look for distinct signals: inclusion, whether you appear; recommendation, whether the model puts you forward; citation, which sources the model used; the count of each gap condition, Omitted, Replaced, Hallucinated, and Zero Leads; and description, how you are characterized. Look for them measured at scale and by geography, not from a handful of manual checks.
The models can differ in the sources they cite, so a platform that reports one number across all of them is hiding the truth. Insist on per-model scoring for each of the four, and on source-level capture, the specific pages each model cited for each prompt. Without the source, a recommendation is a guess.
Ask how sessions are isolated and what context the test retains. NeuroRank uses fresh authentication tokens and context-isolated sessions to reduce carryover from previous NeuroRank conversations. This is a controlled benchmark; account state, location, product surface, and provider behavior can still make consumer experiences different.
For any team that will act on recommendations at scale, ask how execution is governed and verified. Look for a review workflow and a quality check on each recommendation, and for the platform to re-measure after a fix so you can see whether it moved the number. A recommendation that is never verified is a suggestion, not a result.
Ask each vendor for the supported platforms and surfaces, source captures, metric formulas, response exclusions, country coverage, session conditions, implementation responsibilities, and review process. Compare a dated sample under the exact plan being considered. A documented answer is stronger evidence than a broad full-loop label.
Stop paying for clicks that do not convert. Benchmark your AI visibility today with the world's most advanced seo ai tools.
Book a Strategic NeuroRank BriefingAsk for a permitted example containing the prompt, platform and surface, country, capture date, response, citation URLs, classifications, and eligible denominators. Review how exclusions and repeated runs are represented. The export should let a reviewer trace a reported result to evidence rather than rely only on a dashboard screenshot.
Ask when the data was captured, which prompt pool and markets it covers, and whether the buyer can inspect original responses and methods. Keep a historical database separate from fresh brand-specific testing. Both may be useful, but their scope and suitability for the buyer’s decision should be explicit.
Use a defined buyer task and evaluate evidence access, classification clarity, reporting scope, and the workflow for acting on a finding. Record the limits of the trial. A short demonstration can establish usability and method transparency while longer-term outcome claims require evidence over the relevant period.