ComparisonJuly 29, 2026
AI visibility tools compared: which platform measures, fixes, and approves
Ambika SharmaFounder and Product Architect, NeuroRank.
Founder and Product Architect, NeuroRank.
Subscribe for Newsletters
Updated July 2026 · Ambika Sharma, Founder and Product Architect,
Jellyfish's Share of Model platform and NeuroRank ask the same first question, how the models perceive the brand; NeuroRank asks it with fresh-token runs on every prompt cluster, per country, then corrects what it finds. They differ on the operating model: agency-integrated research inside one of the world's leading marketing groups, or an independent governed practice at a published price. This comparison covers both platforms' published capabilities as of July 2026; it does not evaluate unreleased roadmaps.
The comparison matters because Share of Model helped open this category: it was among the first platforms to treat LLM perception as a brand metric, and the question it raised is the one every buyer now asks next: once perception is measured, who corrects it, and how.
Share of Model is a platform from Jellyfish, part of The Brandtech Group, launched in December 2024 per its published announcements. It analyzes how large language models perceive brands, products, and services, citing models such as ChatGPT, Google's Gemini, and Meta's Llama, reports LLM-specific metrics including its share of voice measure, perceived strengths and weaknesses, and top sources of brand visibility, and is designed to close the loop from LLM research into digital marketing strategy through Jellyfish's services, with public training workshops and no published price list.
Share of Model brought perception research into this category early and did so from inside an agency group. NeuroRank measures perception for a different purpose: to correct it. Every reading turns into a ranked fix, an approval, a conditioning cycle, and a tracked result the brand keeps.
These are not the same purchase. One is research that feeds an agency relationship; the other is an independent practice any brand or agency can run.
Unlike Share of Model's research-to-strategy loop, NeuroRank runs the correction itself as a governed cycle: ranked fixes, optional named approval, RAG Conditioning, and tracked lift, independent of any single agency relationship.
Share of Model and NeuroRank bracket this category's history. Jellyfish's platform, launched in December 2024, was among the first to treat LLM perception as a brand metric: how ChatGPT, Gemini, and Llama perceive brands, their perceived strengths and weaknesses, and the sources behind visibility, closed into marketing strategy through The Brandtech Group's services. NeuroRank, the patent-pending AI visibility intelligence platform, is what the category matured into: fresh-token runs on every prompt cluster, per country, across ChatGPT, Gemini, Claude, and Perplexity, every gap classified, ranked fixes, optional named approval, conditioning, and tracked lift, independent, at a published price. Research opened the question; the practice answers it.
Share of Model, from Jellyfish and The Brandtech Group, was among the first platforms to measure LLM brand perception
Its published model list cites ChatGPT, Gemini, and Llama; research closes into strategy through the group's services
NeuroRank is independent: any brand, and any agency, can run the governed practice at a published price
NeuroRank measures live at fixed depth: fresh-token runs on every prompt cluster, per country, across the models in each plan
Beyond measurement, NeuroRank prescribes, offers optional named approval, conditions the sources AI models retrieve, and tracks the lift
NeuroRank needs no access to internal systems
| Share of Model | NeuroRank | |
| What it is | LLM perception research platform from Jellyfish, The Brandtech Group | Patent-pending AI visibility intelligence platform running Model Preference Engineering |
| Primary audience | Brands working with Jellyfish and the group's services | CMOs, media and performance teams, SEO and digital leads, agencies |
| Measurement method | LLM perception analysis per its published materials | Fresh-token runs on every prompt cluster, per country, tracked daily |
| Engines covered | ChatGPT, Gemini, and Llama cited in its published materials | ChatGPT, Gemini, Claude, Perplexity, plus Combined Synthesis |
| Gap classification | Perceived strengths and weaknesses, and source analysis | ORHL: Omitted, Replaced, Hallucinated, Zero Leads |
| Prescriptions | Research closed into marketing strategy through the group's services | Source-linked fixes ranked by impact, tied to the exact prompt |
| Approval workflow | None published | Maker-Checker: named approver, 38-point checklist, auditable trail |
| RAG Conditioning | Not a published capability | Model Conditioning Loop at prompt-cluster level |
| Improvement tracking | Perception metrics over time per engagement | Brand Inclusion Score and citation footprint, month on month, against baseline |
| Executive reporting | Research reporting plus public training workshops | Command Center with formulas shown, plus Deep Insights copilot |
| Compliance | Agency-group engagement terms | No internal-system access |
| Pricing model | No published price list; agency engagement | Published on the NeuroRank pricing page |
Source: NeuroRank analysis of both platforms' published documentation, July 2026.
Both platforms take model perception seriously; they instrument it for different next steps.
Pros:
Among the first platforms to measure how LLMs perceive brands, products, and services, per its December 2024 launch materials
Reports perceived strengths and weaknesses and the top sources behind brand visibility, a genuinely useful research pair
Llama coverage is distinctive: Meta's models sit on its cited list alongside ChatGPT and Gemini
Cons:
Claude and Perplexity are absent from the models cited in its published materials
The published loop closes into marketing strategy through the group's services; a governed fix-and-verify cycle is not the published product
Pros:
Fresh-token runs on every prompt cluster, per country, across ChatGPT, Gemini, Claude, and Perplexity, each a new session with no prior conversation history
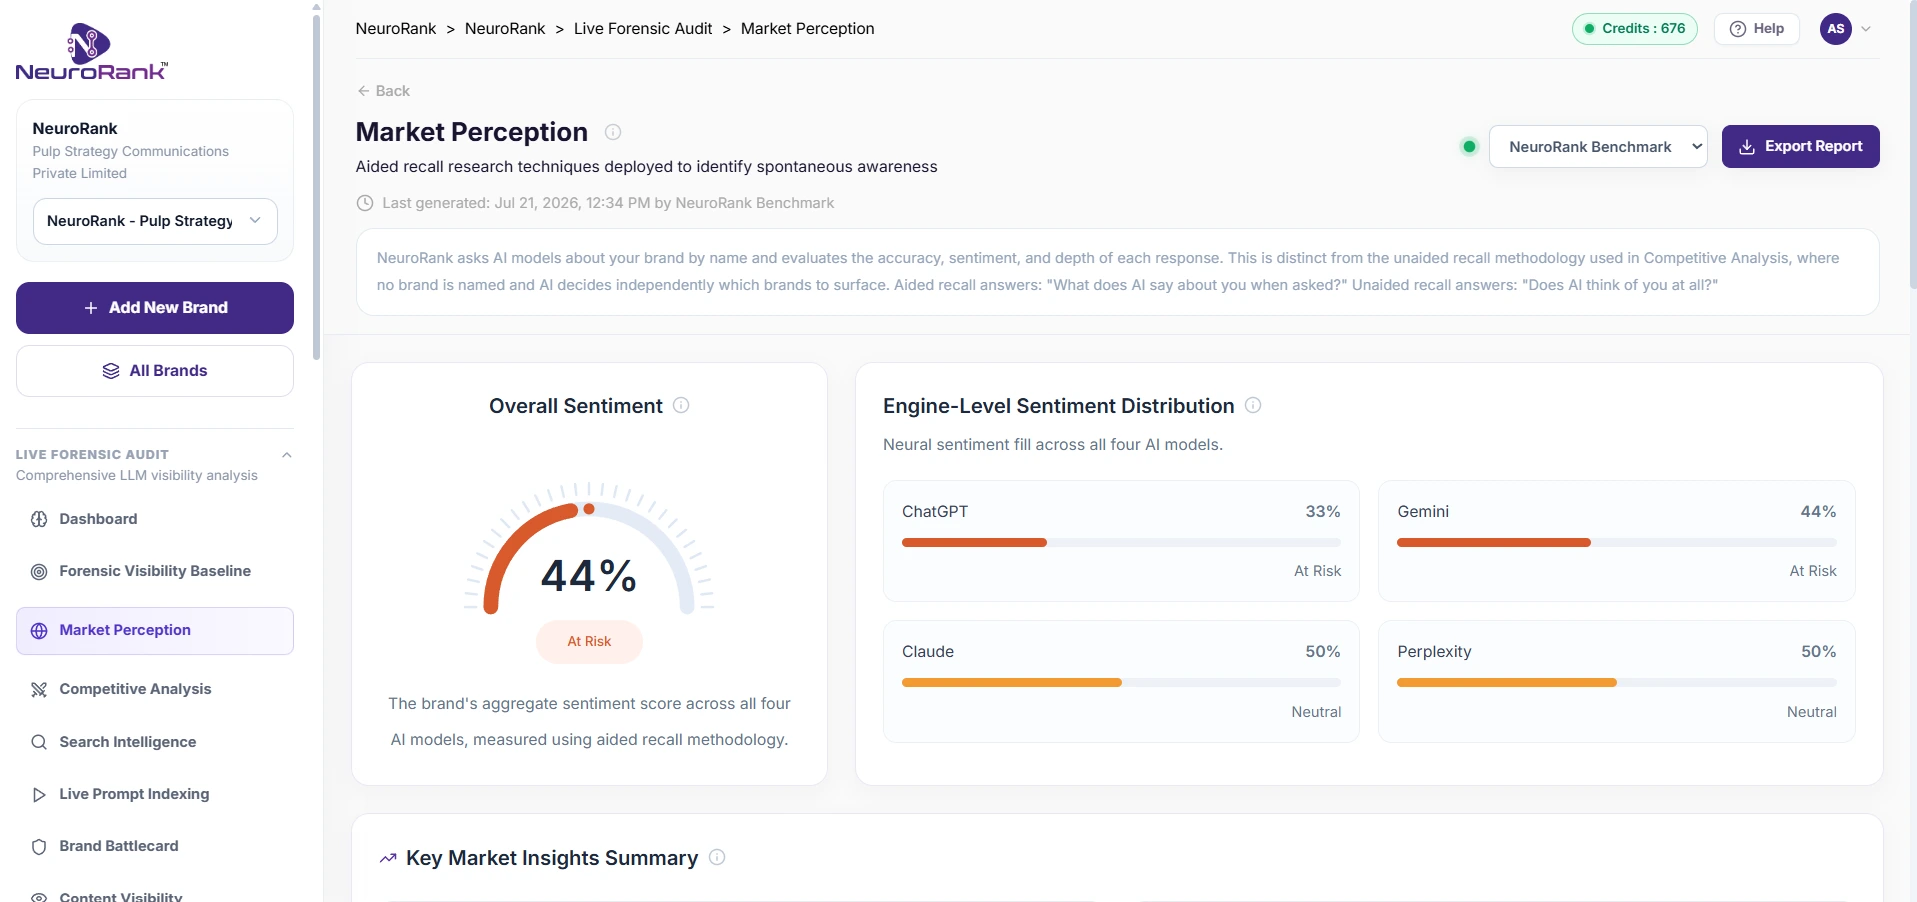
Market Perception applies aided and unaided recall research to the models, and the Brand Battle Card scores category answers across six proprietary dimensions
Every gap classified as Omitted, Replaced, Hallucinated, or Zero Leads (ORHL), with every cited source identified and catalogued
Cons:
Meta's Llama is not covered; the four-model scope is a depth decision
Share of Model reads perception the way brand trackers taught the industry to: strengths, weaknesses, and sources, closed into strategy. NeuroRank reads the same layer for correction: classified gaps, named sources, and a fix queue ranked by impact. One informs the plan; the other runs it.
The structural difference is where each platform lives, and it is worth stating without prejudice: both structures serve real buyers.
Pros:
The loop from LLM research into activation runs inside one relationship, with the resources of The Brandtech Group behind it, per its published materials
Public training workshops give teams a structured entry into the discipline
Cons:
Access runs through the Jellyfish relationship, with no published price list
Brands and agencies outside that relationship cannot run the platform independently
NeuroRank: the independent governed cycle
Pros:
Any brand can subscribe directly at a published price, and any agency can run the practice for clients: multi-client, client-shareable reports are expressly permitted under the acceptable use policy
The full cycle is the product: ranked prescriptions, Maker-Checker approval against a 38-point checklist, the Model Conditioning Loop placing corrected information across owned, earned, and third-party sources, and month-on-month tracking
Cons:
NeuroRank does not write or publish content for you; it prescribes, and your team or your agency implements
Share of Model belongs to brands inside a Jellyfish relationship, and serves them with a group's depth. NeuroRank belongs to whoever runs it: the brand directly, or any agency, with the approval record staying in the client's hands. Several agencies already use NeuroRank to win business and strengthen their own GEO offerings, which is the independence working as designed.
Share of Model's published metrics, perceived strengths and weaknesses and top visibility sources, read like classic brand-tracker research applied to LLMs, which is its lineage and its strength. NeuroRank reads the same layer with a corrective lens: Market Perception applies aided and unaided recall research to the models, the Brand Battle Card asks the models about your category without naming you and scores the answers across six proprietary dimensions, and ORHL classification, Omitted, Replaced, Hallucinated, or Zero Leads, separates being absent from being misdescribed, which are different problems with different fixes. A strengths map tells you how the models feel; a classified gap tells you what to change. Three different problems need three different fixes, and NeuroRank tells you which problem you have, per model, per country.
Share of Model's design center is the brand inside a Jellyfish or Brandtech Group relationship: LLM perception research with early-mover credentials, closed directly into that relationship's strategy and activation, with public workshops as the on-ramp. For those buyers, the integration is the value.
Research delivered through an agency relationship is read in a review meeting. A practice run in-house is read continuously. This section is about which of those your team actually needs.
For the CMO, the Command Center is the executive layer: four headline metrics tracked against the Month 1 Baseline, each card showing the formula behind its number, a heatmap of how much of the brand's possible AI surface is actively governed, and a one-click report export. Because every change approved through Maker-Checker carries an approval record, the CMO can present the improvement to the board with the evidence behind it.
For media and performance teams, two instruments connect AI visibility to the plans they already run. Keyword Intelligence maps top Google keywords and volumes by country into eight customer-intent journeys, roughly 180 keywords per workspace with difficulty and opportunity scoring, so search demand and AI presence read as one picture. The Citation Tracker classifies every source the models cite as branded, competitor, industry, social, or negative, which tells earned media and PR exactly where placement effort will move the models.
For SEO and digital leads, the diagnostic depth above is the daily surface: live evidence, classified gaps, ranked prescriptions, and month-on-month tracking.
For agencies, NeuroRank's Enterprise plan covers multiple brands. Client-shareable reports are expressly permitted under its acceptable use policy, and no access to a client's CRM, analytics, or internal systems is ever required, because the platform probes the models from the outside, the way a customer would. That shortens both the pitch and the security review.
Share of Model fits the brand that wants perception research inside its Jellyfish relationship. NeuroRank fits the CMO, the media team, the SEO lead, and any agency, that want an independent governed practice with the record in their own hands. The category owes the first structure its start; buyers now get to choose the second.
Research delivered through an agency relationship is read in a review meeting. A practice run in-house is read continuously. This section is about which of those your team actually needs.
Pros:
Research outputs and workshop-led enablement suit brand and insight teams, per its published materials
The Brandtech Group relationship carries enterprise account structures
Cons:
No approval or audit layer is published; the platform's job ends at research and strategy input
Reporting scope and access follow the engagement rather than a published product tier
Pros:
Research reporting arrives as a deliverable. NeuroRank's reporting is live: baseline-tracked metrics with the formula shown, an execution-health view of where implementation is slowing, and a one-click export.
Deep Insights, a conversational copilot scoped to your own audit data, answers questions across every section of the report and keeps the chat history
Every platform action is attributed in a usage ledger, to a person, a role, a timestamp, and a category, and reviews carry service-level indicators, so an enterprise sees not just what changed but how the team is running
Onboarding reads your existing footprint: the Brand Discovery Panel ingests your sitemap, LinkedIn presence, and llms.txt, and Makers work with CSV import and export
The practice runs without access to your internal systems, which shortens security review
Cons:
The dashboards are purpose-built for the practice rather than a general BI layer; no Looker Studio connector is published
Leadership gets numbers it can read and defend: baseline-tracked metrics with the calculation shown behind every number, and an approval record behind every change routed through Maker-Checker. Procurement gets a platform that needs no access to any internal system.
NeuroRank was stress-tested with 150+ brands and 150+ leadership teams across 65 industries before opening globally.
The agency channel adds a public proof point. Per NeuroRank's May 2026 launch announcement, several agencies use the platform to win new business and strengthen GEO offerings, and one agency onboarded three enterprise clients across the automobile and BFSI sectors. Client references in NeuroRank's external materials stay at sector level by policy: claims carry their evidence, and evidence carries its limits.
Share of Model has no published price list; access runs through Jellyfish engagement, with public training workshops the visible entry point, per its materials as of July 2026. Verify terms with Jellyfish directly.
NeuroRank's plans and prices are published on its pricing page. The architecture compounds in the buyer's favor: one new prompt cluster is confirmed each month and every earlier cluster is re-run, so month twelve tracks twelve clusters against a continuous Baseline, and the dataset becomes an asset that switching away would abandon. And because the plan price stays fixed while the cluster count grows, the effective cost per active cluster falls month by month.
Lists of Share of Model competitors mix monitoring platforms with full-cycle platforms. Five questions separate them. Is the platform independent of a single agency relationship, or integrated with one? Does the platform prescribe fixes or only report and suggest? Who approves work before it goes live, and is the record exportable? Can it see perception, including factual errors about your brand? Can you verify the methodology on your own brand first? NeuroRank answers all five in writing, on every plan.
One fact frames the whole decision: the models keep answering buyer questions every day with whatever they currently believe about your brand, so the choice between the two platforms is really a choice about how quickly those answers get corrected.
In NeuroRank's stress test with 150+ brands and 150+ leadership teams across 65 industries, perception gaps rarely traveled alone: the same brands showing weak associations were also being skipped, replaced, misdescribed, or missed entirely in live answers. Knowing how the models feel about a brand does not slow what they say about it tomorrow.
The correction is a bounded monthly practice. Research cycles inform the next plan; the governed cycle changes the next answer.
Share of Model is the right choice for brands working with Jellyfish and The Brandtech Group that want LLM perception research closed directly into that relationship's marketing strategy, from a platform with genuine early-mover credentials.
If your team needs the question after measurement answered, what do we fix, in what order, approved by whom, with what proof it worked, that is the cycle NeuroRank was built to run. It runs the full cycle: live evidence at fixed depth, prescriptions linked to source pages, optional named approval, RAG Conditioning of the sources AI retrieves, month-on-month lift against a baseline, and an executive layer the CMO can read in one screen.
"I built NeuroRank to address GEO comprehensively, putting control in the hands of the user." Ambika Sharma, Founder and Product Architect, NeuroRank |
Perception research and governed correction answer different questions, and many teams want both.
Stop paying for clicks that do not convert. Benchmark your AI visibility today with the world's most advanced seo ai tools.
Book a Strategic NeuroRank BriefingA Jellyfish platform, launched in December 2024, that analyzes how large language models perceive brands, products, and services. It sits within Jellyfish’s marketing services. (Source: Jellyfish launch release, December 5, 2024.)
Jellyfish, a company within The Brandtech Group. (Source: jellyfish.com, checked October 2026.)
Jellyfish names models such as ChatGPT, Google’s Gemini, and Meta’s Llama, as examples rather than a full list. NeuroRank covers ChatGPT, Gemini, Claude, and Perplexity. (Source: Jellyfish launch release, December 5, 2024.)
Jellyfish does not publish a price. Share of Model sits within Jellyfish’s marketing services, so contact Jellyfish for scope and terms. NeuroRank plans are on neurorank.ai/pricing.
On this page it names Jellyfish’s product. NeuroRank uses its own named measures: Brand Recommendation Score, Brand Inclusion Score, Brand Citation Score, and ORHL (Omitted, Replaced, Hallucinated, Zero Leads), each defined over tracked responses.
When a team wants a platform it runs itself, rather than research inside an agency service, with every gap classified, source-linked fixes, and daily tracking per country and city.
Who runs it: Jellyfish delivers Share of Model within its marketing services, while NeuroRank is a platform your team or agency runs. Then compare published pricing, the AI models named, whether every gap is classified and given a fix, and whether results are tracked by country and city.
Evertune for brand research with media, and Profound, Peec AI, and NeuroRank for platform-based tracking. Each is compared on this site.